
A few words
Match words in titles, URLs and folders, including Chinese substrings.
“sqlite vector index”
Turn your browser bookmarks into a searchable personal library. Search by keywords, describe what you remember, or browse by date. Your library lives on the computer or server where you run facetmark.
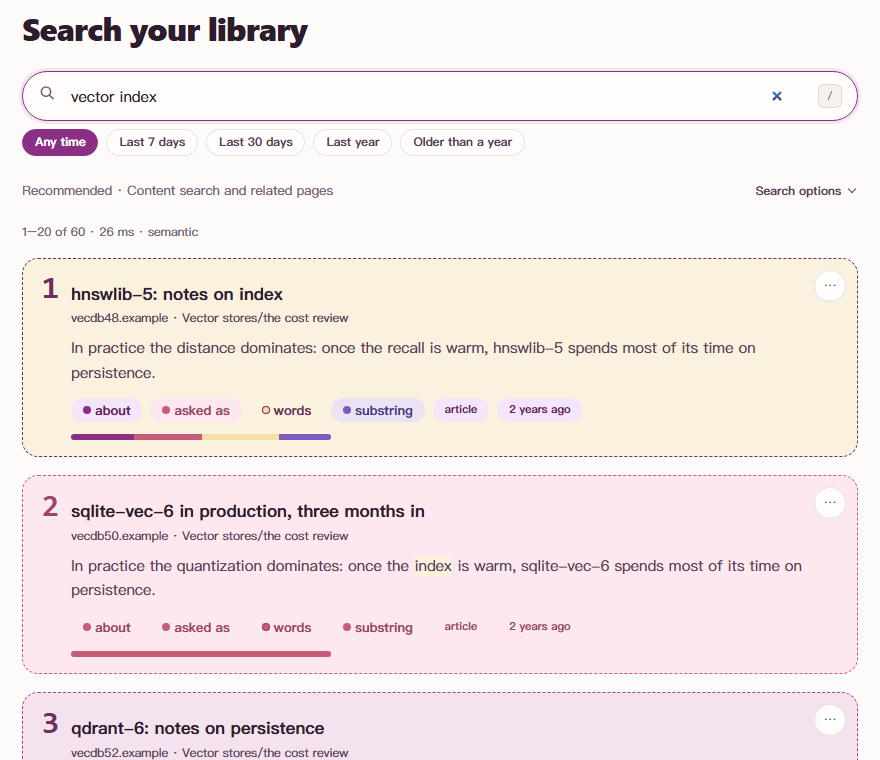
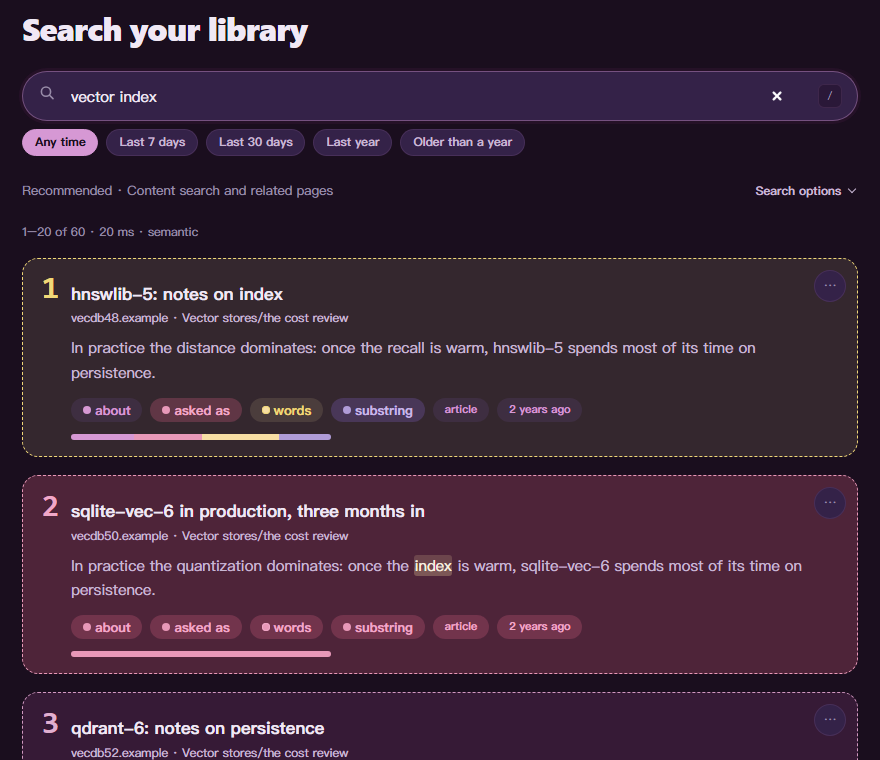
You do not need a perfectly organised folder tree. Start with keywords, add an embedding model for searches in your own words, and use dates or related pages to narrow things down.
Match words in titles, URLs and folders, including Chinese substrings.
“sqlite vector index”
With an embedding model, describe the content you need. Results depend on your indexed text and model.
“search that works without a connection”
Filter by save date, then explore other bookmarks saved in the same session.
“database articles saved last month”
The retrieval methods and their limits are documented. Read the evaluation methods and results.
Install with Python 3.10+, import your bookmarks, then open the app. The full tutorial covers models, indexing, local use and server access.
python -m pip install facetmark
facetmark import
facetmark index --no-fetch
facetmark serve
Just exploring? Run facetmark demo for a synthetic offline library. No API key required.
--no-fetch skips page downloads; existing stored text can still be used.facetmark index.facetmark demo, which builds a 60-page synthetic library offline. Provider is mock, so this is a plumbing check, not a quality measurement — the mock hashes text into vectors. The score column is not sorted because the rank comes from stage E and the score is the fusion score, which stage E deliberately does not overwrite.Content vectors, generated questions, keywords and substrings offer different retrieval signals. With embeddings configured, the default uses content vectors, graph expansion and time decay. Compare other combinations in search options; lexical search remains available without a model.
| Facet | What it indexes | Answers | Default |
|---|---|---|---|
| Lexical two FTS5 indexes | Character trigrams and word segments of the title, URL and body. | Exact strings, identifiers, code, error messages, and Chinese text that has no spaces to tokenise on. | off cost 5.4pp when fused |
| Content dense vector | An embedding of the extracted page body, not the title. | Paraphrase. The idea you remember when the words are gone. | on W1 winner, 0.643 |
| Intent generated queries | Candidate questions a model writes for the page, kept only if searching them actually retrieves the page back. | Why you would come looking, phrased the way you would phrase it later. | off 38% of intents plausible |
| Context sessions and graph | Save-session clustering, domain structure, and a link graph over the library. | “What did I save around that one?” | graph on gate off +2.09pp / −18.83pp |
Every one of those four verdicts links to a protocol, a query set and a confidence interval on the measured page.
The coloured stages are what runs in the shipped default profile. The grey ones are built, tested and switched off. Every indexing stage is idempotent and fingerprinted, so facetmark index re-runs only the work whose input changed.
four facets, in parallelone of them is on by default
branches off the fusion step
shipped default pathbuilt, wired, off by default
bookmark → fetch → content → enrich (summary, topics, entities, key points) → embed → intents → filter → sessions → edges.
Enrichment is keyed on the body hash; embedding is keyed on the reconstructed embed text, so a vector that no longer matches its text is detected rather than trusted. --force ignores both.
One hop out from the fused hits, returned as a separate group rather than mixed into the ranking. Measured at +2.09pp, 10 wins and 0 losses, 9 ms.
Inspect result summaries and sources, synthesise an answer with citations, and check how much of your library has been fetched and indexed. The same interface works on desktop and mobile.
domain:github.com, tag:work, added:<7d, -pinterest, sort:date — in the same box, with completion for the field names and the values that exist in your library. A query that is only filters is a browse: no model call at all.
The token is fetched from a route that answers only when the caller and the address in the request are both loopback, so on your own machine there is nothing to copy. Anywhere else the page asks you to paste it once.
An empty library prints the import command. Bookmarks with no vectors print facetmark index. A search with no hits and a full fetch queue tells you that, instead of showing you an empty list and letting you guess.
One switch in the header, remembered between visits. Light, dark, or whatever your system is set to. / focuses the box, the arrow keys walk the results, Esc clears.
Manifest V3. Host permissions are http://127.0.0.1:8787/* and http://localhost:8787/*. It reaches your own machine, pairs with a token, and never writes to your browser's bookmark store.
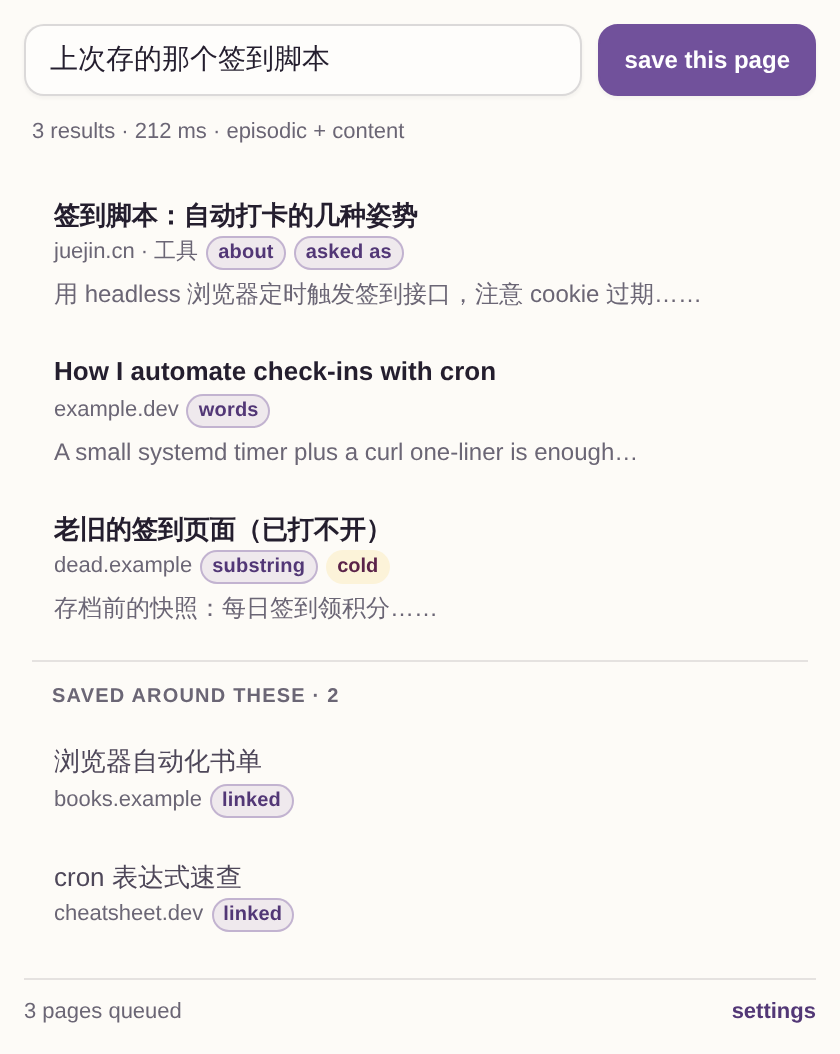
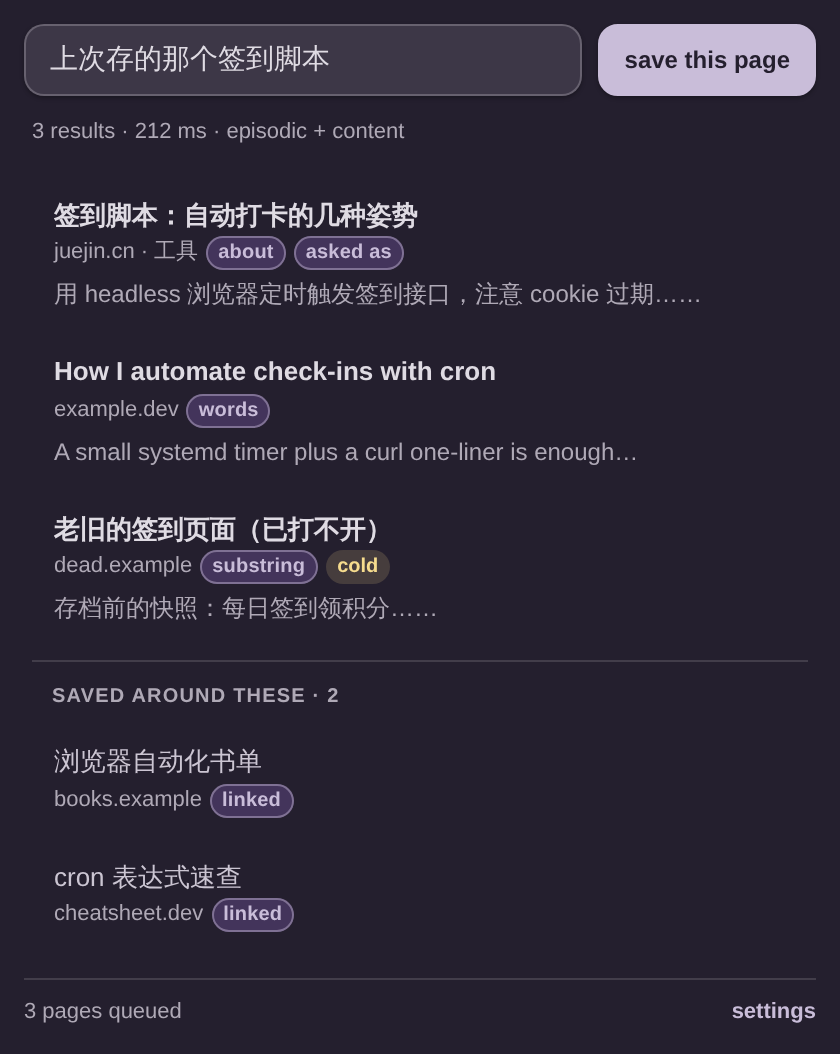
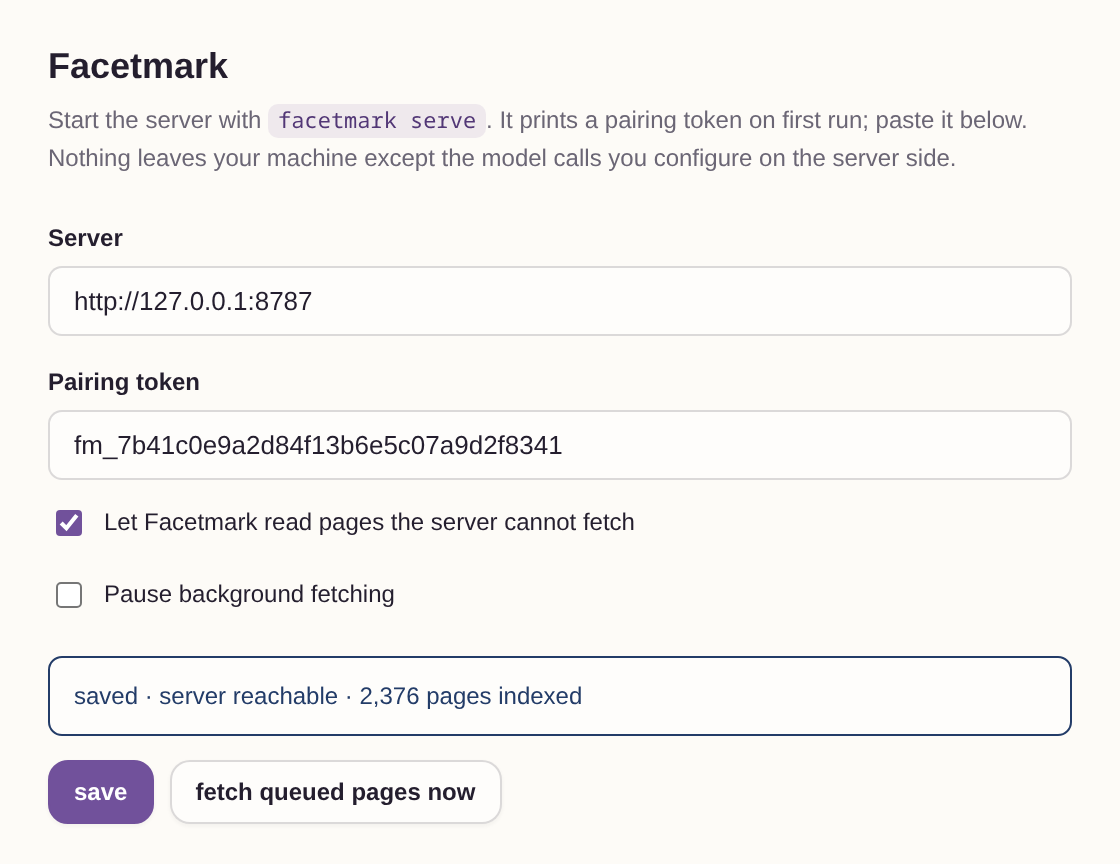
facetmark health says why.These are UI previews rendered against mock data, not screenshots of a real library — a real one would put somebody's browsing history on a public page.
The interesting part of this project is not the features that worked. It is the ones that were built, pre-registered, measured, and then turned off — including one that had already shipped.
Three criteria were registered before the run. All three failed. Fusion cost 5.4 percentage points of Recall@5 and made queries 3.5× slower — 148 ms at p50 became 526 ms. The four-facet default was withdrawn the same day.
Two things did survive that run and are shipped: graph expansion as a separate result group (+2.09pp, 10 wins, 0 losses, p=0.0019) and the reranker on Recall@1 (+4.80pp, CI95 [+1.46, +8.35]).
Then there is the episodic gate. It won its holdout (+3.09pp, 19 wins, 0 losses, p=3.8e−6) and shipped. A 361-query probe set built afterwards to ask what it does when it fires on the wrong query answered −18.83pp, 3 wins against 71 losses. The default was reverted.
facetmark serve hosts a search page at /app. Search and a library overview, English or Chinese, light or dark. The only interface that needs nothing installed beyond facetmark itself.
Twenty-one commands. search takes --explain to print which facet matched, and --config to run any ablation rung by name.
facetmark serve binds 127.0.0.1:8787. Twenty-nine routes. Four are open — the root, health, and the two the local page needs to load itself; everything that touches the library requires a pairing token.
facetmark mcp speaks MCP over stdio. Nine tools and three resources, so Claude Desktop can search your library and read a saving session.
MV3. Omnibox keyword fm, Ctrl+Shift+K, one-click save with a local indexing queue.
A search-provider plugin that puts facetmark behind karakeep's own search box. The wire contract is pinned by a replay test.
The library stays on the machine running the service. Fetching contacts saved websites; online models receive the relevant text and queries. Importing through a server deployment transfers your file to that server.
A local embedding model computes on that machine after its files are downloaded. Online chat calls depend on your configuration. facetmark provides no hosted accounts or central storage service.
No. Import is a one-way read. The importer opens the profile's Bookmarks file or your exported HTML, reads it, and closes it. Nothing in the codebase writes to a browser profile.
Nothing is deleted on the facetmark side either. The decay layer demotes stale pages in the ranking; it never removes a row.
Yes, and it will be worse, and it will tell you so. Without a model you keep both lexical facets and the whole session and domain graph. You lose the content facet — the one that measured best — and the intent facet.
A middle path: run a local embedding model for the content facet and skip the chat model. You lose enrichment summaries and generated intents, keep paraphrase search.
Cost depends on page count, text length, model and provider pricing. Validate the connection and results with a small import before processing your full library.
Fetching also depends on site response times, access restrictions and per-domain rate limits. Later runs reuse unchanged stages; stored vectors and fetched page bodies are separate states.
Because four-facet fusion was measured on 479 real queries and came out 5.4 points of Recall@5 behind the content facet on its own, at 3.5× the latency.
The mechanism is written up: flat-weight RRF lets a coincidence on two weak facets (0.0279) outvote confidence on one strong facet (0.0164). The facets still exist and are still tested. --config C turns them all on if you want to see it for yourself.
For people who want to manage their own bookmark data, rediscover saved material and run a local or self-hosted tool. CLI, HTTP API and MCP interfaces connect it to existing workflows.
Public evaluation queries were written by the project author. Check the results on your own bookmarks; one dataset is not a quality guarantee.
Import never writes back. Your folder tree is yours.
The cold layer demotes. It does not remove rows, and facetmark health shows you what it considers dead and why.
One SQLite file you can open with any SQLite browser. If you stop using facetmark your data is still readable.
robots.txt is honoured, per-domain concurrency is capped at 2, there is a minimum interval between hits on one host, and the user agent says what it is.
And no default change without a query set that was frozen before the run.
Start with a small set of bookmarks. Once your first search works, add models and integrations as you need them.